AI Product ManagerBased in India

Sabyasachi Mishra.

A product mind and a builder’s instinct. I build AI products and stay close to what happens after they ship.

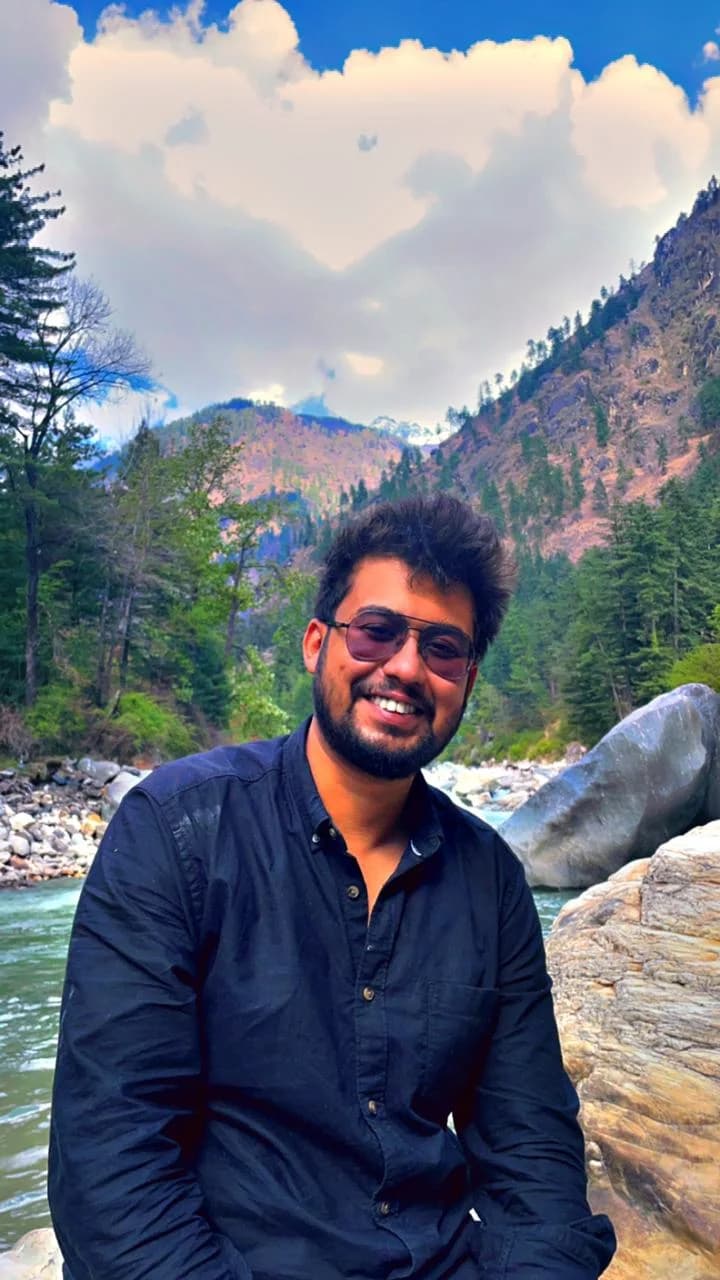
Sabyasachi Mishra outdoors in the mountains
40K

leads handled monthly

Voice AI
48×

faster audit cycle

Vision systems
22

operating cities

Live compliance
₹40K Cr

portfolio monitored

Enterprise NLP

Work shipped at Stanza Living, Power Finance Corporation, and Brahmagupta Edu.

Selected work

Complex problems. Considered decisions.

A selection of AI products I’ve shaped, from everyday conversations to decisions where trust matters.

Voice AI · Lead conversion

Lead Qualification Voice Calling Agent

A voice agent designed to know when the conversation should no longer belong to the model.

The agent handles a high-volume lead journey in the language people actually use: fluid Hindi-English conversation, with explicit routes back to a human when confidence or sentiment drops.

Read the story

The defining decision

Make confidence-led human handoff a first-class product state, with conversation context preserved.

AI Product Manager · Stanza Living, 2025-26

40K
leads handled each month
60 / 40
Hinglish code-switching pattern
HITL
confidence-based routing
  • LLM
  • Voice
  • Human in the loop
  • Drift

Stanza Living · Operational AI

Operational Data Copilot

From business questions to operational clarity.

I led two developers and partnered with Data Science to build a React-based copilot for Business and Functional Heads. We built the agent harness around memory and context engineering, combining natural-language data access with support for ground-team updates and communication.

Read the story

The defining decision

Build the harness around the operational workflow, with memory and context at its core.

AI Product Manager · Stanza Living

Led with 2 developers, in collaboration with Data Science

  • AI Agents
  • NL2SQL
  • Context engineering
  • Internal tools

Computer vision · Operations

Vision-based compliance

Turning a 12-hour inspection lag into a near-real-time operating signal.

A VLM-based audit loop evaluates housekeeping evidence, routes uncertain cases to review, and gives operators a daily view of compliance across a distributed network.

Read the story

The defining decision

Use a 65% confidence gate for human QA and treat drift alerts as part of the product loop.

AI Product Manager · Stanza Living, 2025-26

48×
faster audit cycle
+35%
increase in coverage
400+
stakeholders on live data
  • VLM
  • Computer vision
  • CPU inference
  • Monitoring

Enterprise NLP · Credit risk

Risk intelligence platform

Making early-risk signals legible inside a regulated, document-heavy workflow.

An NLP system surfaces risk events from unstructured financial documents, then delivers them through role-aware interfaces designed for the people accountable for the portfolio.

Read the story

The defining decision

Structure risk signals for accountable review, with PII masking and role-aware access built into the workflow.

Assistant Product Manager · Power Finance Corporation, 2023-25

₹40K Cr
portfolio monitored
85%
document parsing automated
~20%
risk exposure flagged early
  • NLP
  • NER
  • PII masking
  • Role-based access

Good products are a seriesof thoughtful decisions.

Reliability lives in the boundaries: what good means, when the system should act, when a person should step in, and how the product learns after launch.

An editorial map of evaluation sets, confidence handoffs, guardrails, and learning loops drawn as one connected system.

Define good before writing code.

An AI feature without an evaluation set is a demo with a roadmap. I establish the measurable boundary first, so the team knows what should ship and what should not.

Design the handoff, not just the happy path.

Confidence routing is a product decision. Models handle what they can; people handle what they cannot. The quality of that boundary often decides whether the system earns trust.

Guardrails belong in the architecture.

PII masking, access control, tone constraints, and adversarial thinking shape the system from day one. Trust is not a QA ticket at the end of a sprint.

Treat drift as a product bug.

Production models degrade quietly. Monitoring, feedback loops, and retraining triggers need owners and thresholds just like any other critical product behaviour.

Independent projects

Made out of curiosity.

Small frustrations turned into things you can use. Conceived, designed, built, and looked after by me.

Live

Visual feedback for coding agents

Shiproom

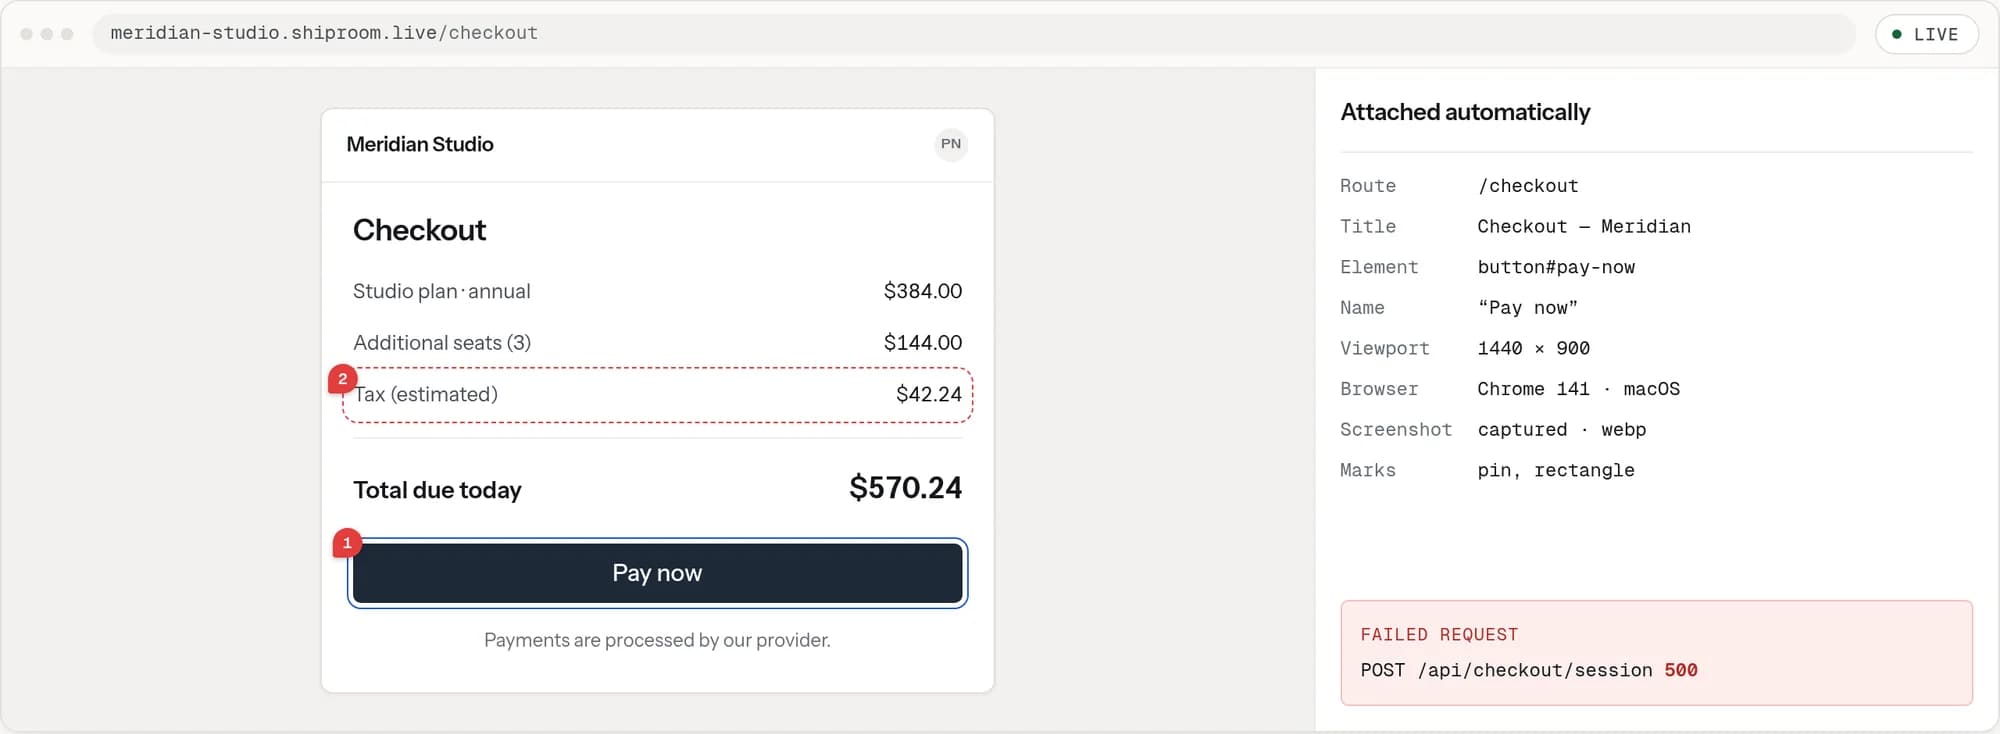
“The button feels broken” is not a bug report. Someone still has to turn it back into a route, an element, and a browser, usually afterwards, without the screen in front of them.

Product decision

A PM owns the quality of the evidence handed from a user to a builder, not only the interface that collects it.

Open shiproom.live (opens in a new tab)
The Shiproom reviewer demonstration: a sample checkout page with two numbered reviewer marks on the “Pay now” button and the estimated tax row, beside the context Shiproom attaches automatically: route, page title, selected element, accessible name, viewport, browser, screenshot, mark types, and a failed POST request that returned 500.
The public reviewer demonstration on shiproom.live. Two marks on an invented checkout, and the context that leaves with them.

Live

Local-first teleprompter

teleprompter.wtf

The reliable thing must not depend on the clever thing.

Product decision

Reliability starts with a useful baseline that survives when optional intelligence, permissions, or the network do not.

Open teleprompter.wtf (opens in a new tab)
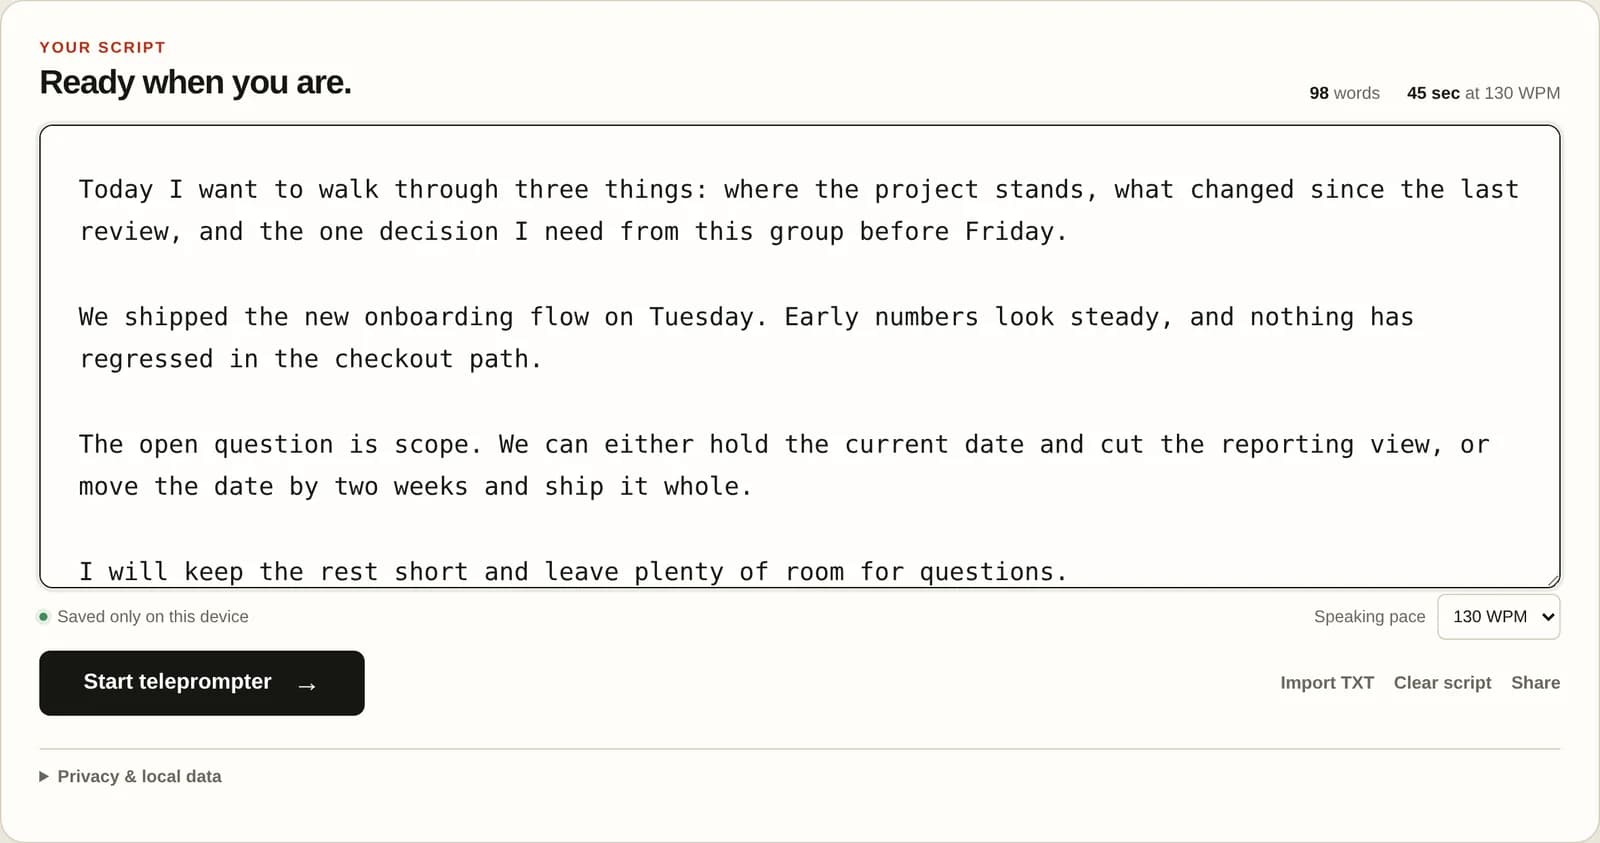
The teleprompter.wtf script editor holding a short neutral rehearsal script, showing a live count of 98 words and an estimated 45 seconds at 130 words per minute, a “Saved only on this device” indicator, a speaking-pace control, and the Start teleprompter action.
The editor, with local word and time estimates.

Live

Precise image workspace

compressimage.fun

An exact size limit is a search problem, not a quality slider.

Product decision

Precise promises require an operating method that proves when a target was met and says clearly when it was not.

Open compressimage.fun (opens in a new tab)
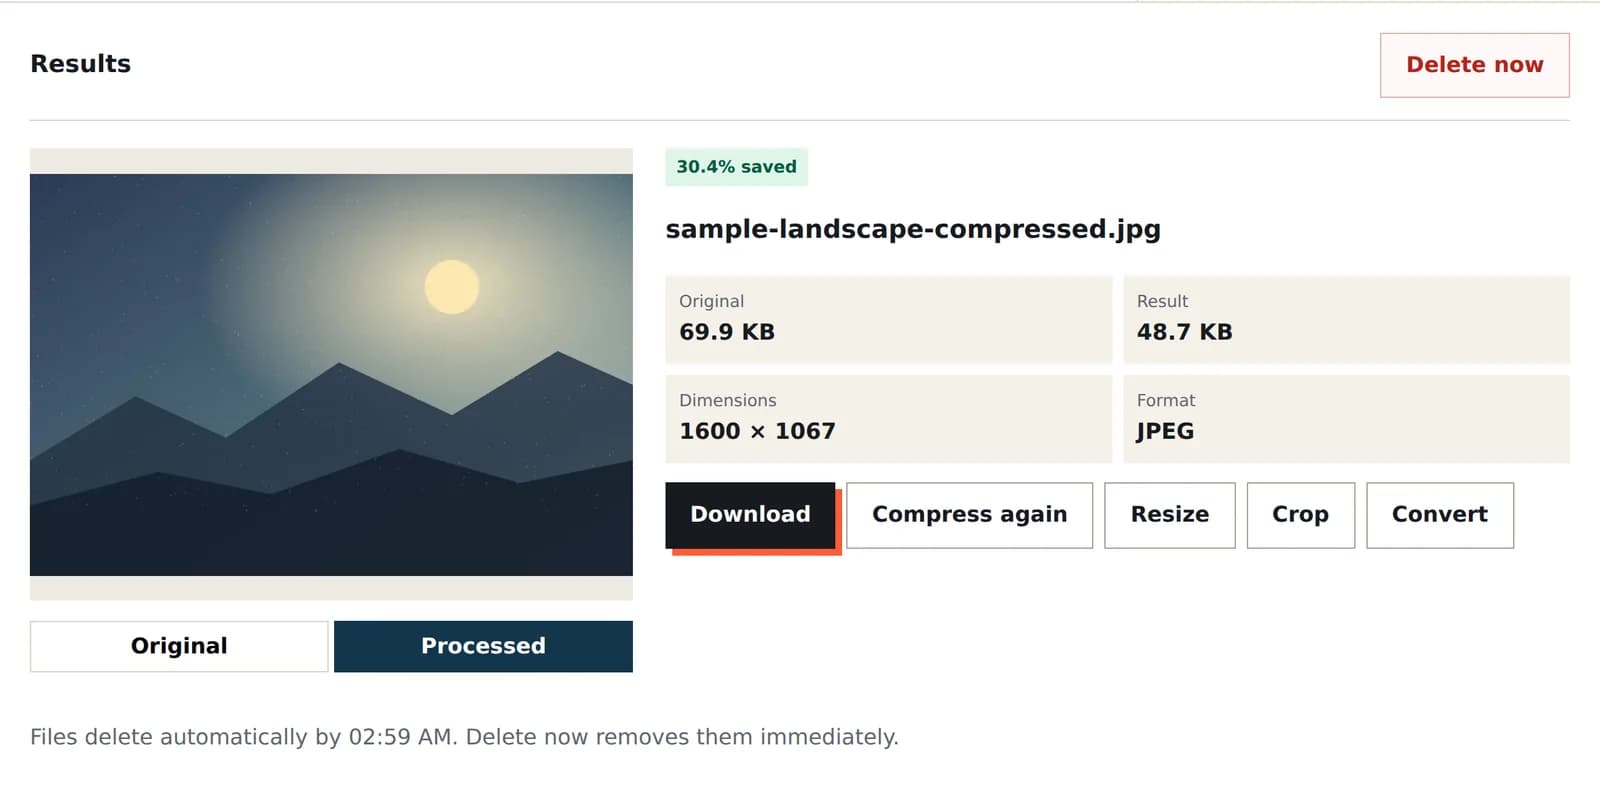
The compressimage.fun result workspace after an exact-size run on a synthetic test image: 69.9 KB reduced to 48.7 KB under a 50 KB cap with the original 1600 by 1067 dimensions kept, an original-versus-processed preview toggle, follow-on resize, crop and convert actions, a Delete now control, and a note that files delete automatically.
One exact-size run on a synthetic test image: 69.9 KB down to 48.7 KB under a 50 KB cap, dimensions intact.

The workshop.

The quieter side of building: the agents, memory, and infrastructure I run for myself. A place to learn by doing.

Questions with working interfaces.

Each one existed to answer a focused product or systems question.

Running

Hook-pattern learning loop

A feedback layer for the content engines that records performance at 2h, 24h, and 7d, then turns useful themes and structures into inputs for the next draft.

A learning loop should record uncertainty honestly. Unavailable is not zero, and fabricated data teaches the wrong lesson.
OpenClawObsidianFeedback loop
Shipped

Small models for high-frequency jobs

A fully local memory loop using a 3B extraction model, local embeddings, and Qdrant to keep agent recall private, cheap, and continuously available.

A frontier model belongs in the conversation; a smaller model can quietly own the narrow, always-on background task.
OllamaQdrantmem0
Testing

AI video pipeline

A production pipeline exploring where generative tooling can compress repetitive video operations without hiding quality decisions.

The unit of automation is rarely the whole workflow; it is the slowest repeatable decision inside it.
MultimodalWorkflow

Ideas sharpened by building.

Notes on the product decisions that sit between a capable model and a dependable system.

NowUpdated August 2026

Still building. Still asking questions.

Lately, I’ve been spending time with autonomous agents, the products I run, and the question of when a system should ask a person for help.

See what I'm exploring

Good conversations start somewhere.

A shared curiosity, an interesting idea, or just a hello. You don’t need a brief to write to me.